
Software has entered the Slop Era.
The cost of producing plausible code has collapsed, but the cost of knowing whether that code belongs in your system has not. Every engineering team using coding agents now trivially generates more code than it can responsibly absorb.
Slop is code that is locally reasonable but globally careless: the fifth copy of a helper function, a try/catch block that hides an error from the error reporter, a session-scoped lock behind a transaction pool, a migration that runs cleanly yet undermines the application’s security model. Slop survives casual review because every line looks plausible, but introduces risk because it lacks knowledge of the system around it.
These problems existed before the Cambrian explosion of code generation. The naive response then, as now, was to demand more careful review. That does not scale. The answer to the Slop Era is not more careful engineers, but engineering discipline made executable.
By discipline, I don’t mean heroics, process theater, or a longer approval chain. I mean taking the judgment a strong engineer carries in their head and putting it into the environment, dependency graph, lint rules, types, tests, comments, and deployment path. The system should supply missing context, reject known mistakes, contain the blast radius, and preserve the reason behind old decisions.
The answer to the slop problem ends up looking a lot like what the best engineering teams have been doing for the past decade: turning convention into constraints. This is not a special set of guardrails for agents - what’s good for humans is good for machines. Both make locally plausible mistakes when they lack context; the difference in the Slop Era is that agents hit these problems often enough to make the return on fixing them impossible to ignore.
Sonora tests whether that discipline can keep up with output. Over the last sixty days, I merged 257
pull requests into main, over six per day on working days. Across the team, 761 PRs landed, an
average of sixteen per shipping day, with a peak of 34. We are a team of five engineers. I remember
entire months at a prior startup, with a much larger team, that did not ship close to what we now do
in a day.
Six PRs in a day would be meaningless if they were six typo fixes. Sonora’s codebase is barely a year old and already runs close to 1 million lines of TypeScript across thirty packages, and a single PR routinely spans a migration, worker jobs, UI, tests, and docs. That is the real stress test: can the system absorb a change that wide without requiring me to inspect every boundary by hand? I’m not typing six times faster. The repository is doing more of the remembering, checking, and rejecting before the change reaches me.
The governing idea is make it cheap to be wrong. AI did not invent this discipline, but it changed the discount rate: work that used to pay back once a sprint now pays back dozens of times a day.
What’s good for humans is good for machines
Fast feedback. One command that does the thing. Errors that explain what to do next. Comments that record why an obvious alternative failed. These were good engineering practices before coding agents, but agents make their value visible because they exercise the system far more often.
Start with the development environment. An agent will confidently reason from whatever world you give it. If that world has the wrong port, a drifting Node version, or somebody else’s database, a green test can certify fiction.
Our environment is a Nix flake. Node, Postgres, Redis, Pulumi, gcloud, kubectl, ShellCheck, and the rest of the toolchain are pinned. Entering the repo starts its services. Ports are allocated per checkout and exported as environment variables, so multiple copies of Sonora can run side by side without sharing a database or guessing who owns port 5432.
This is what loading the repo looks like:
╭──────────────────────────────────────────────────────────────╮│ 🦊 sonora dev ││ ││ ▴ Postgres 127.0.0.1:5432 ││ ▴ Redis 127.0.0.1:6379 ││ ▴ Mailpit 127.0.0.1:1025 → http://127.0.0.1:8025 ││ ▴ App http://app.sonora.localhost:3000 ││ ▴ Worktrees grove · grove --once snapshot ││ ▴ Turbo shared · read-only ││ ││ ✓ ready to build · run pnpm dev │╰──────────────────────────────────────────────────────────────╯The banner is for humans, and we suppress it in non-interactive shells, but the port assignments are
still exported as $PGPORT, $REDISPORT, and $PORT. Our AGENTS.md tells
coding agents to use those variables instead of guessing the defaults. Before every shell command, a
hook puts the agent inside nix develop, so when it runs pnpm test, it gets the same pinned Node
and dependencies I do, along with that worktree’s own Postgres.
Humans are pretty good at noticing when an environment is wrong. We see an unexpected port or version, swear a little, and adjust. But agents are more likely to accept what they see as fact and build the next ten steps on top of it. A passing test in the wrong environment is worse than a failing one because it sends the rest of the work in the wrong direction.
This is also why I have become more opinionated about monorepos. An agent can work only with what exists in its checkout. Put the worker in one repository and the app in another, and any change that spans both becomes a coordination problem. Humans compensate with memory, Slack, and meetings, while agents guess. Neither is a good use of time.
Sonora keeps the application, worker, database package, infrastructure, documentation, supporting tools, and marketing site in one repository. Even this post is a Markdown file in the same repo. The app, worker, database package, and Pulumi infrastructure are all TypeScript, so changes across those boundaries stay in one type system. One recent change added cost visibility to workflows. It touched 27 files across a database migration, worker code, pricing logic and tests, the workflow builder, the credits settings page, and two architecture docs. It was one product change, so it was one PR. I did not need to coordinate three repositories or remember which part had shipped.
Keeping everything together does not mean every change runs every test or deploys every application. Turborepo already knows the dependency graph. CI uses it to determine which packages need checking, and the deployment pipeline uses it to determine whether production code changed. Editing this post republishes the marketing site and stops there. Without that filtering, changing this sentence would run the entire application suite. We lean on the dependency graph to keep changes isolated and checks targeted.
Conventions are stronger as constraints
Conventions aren’t actionable in their natural state. They’re just a shared understanding; a piece of advice. Teams have spent a decade trying to make a codebase read as though one person wrote it. That consistency now has a functional purpose: agents learn from the nearest example. Engineering discipline becomes executable when violating the convention produces immediate, specific feedback. The job is to move judgment out of reviewers’ heads and into mechanisms that can reject a change. We use this ladder:
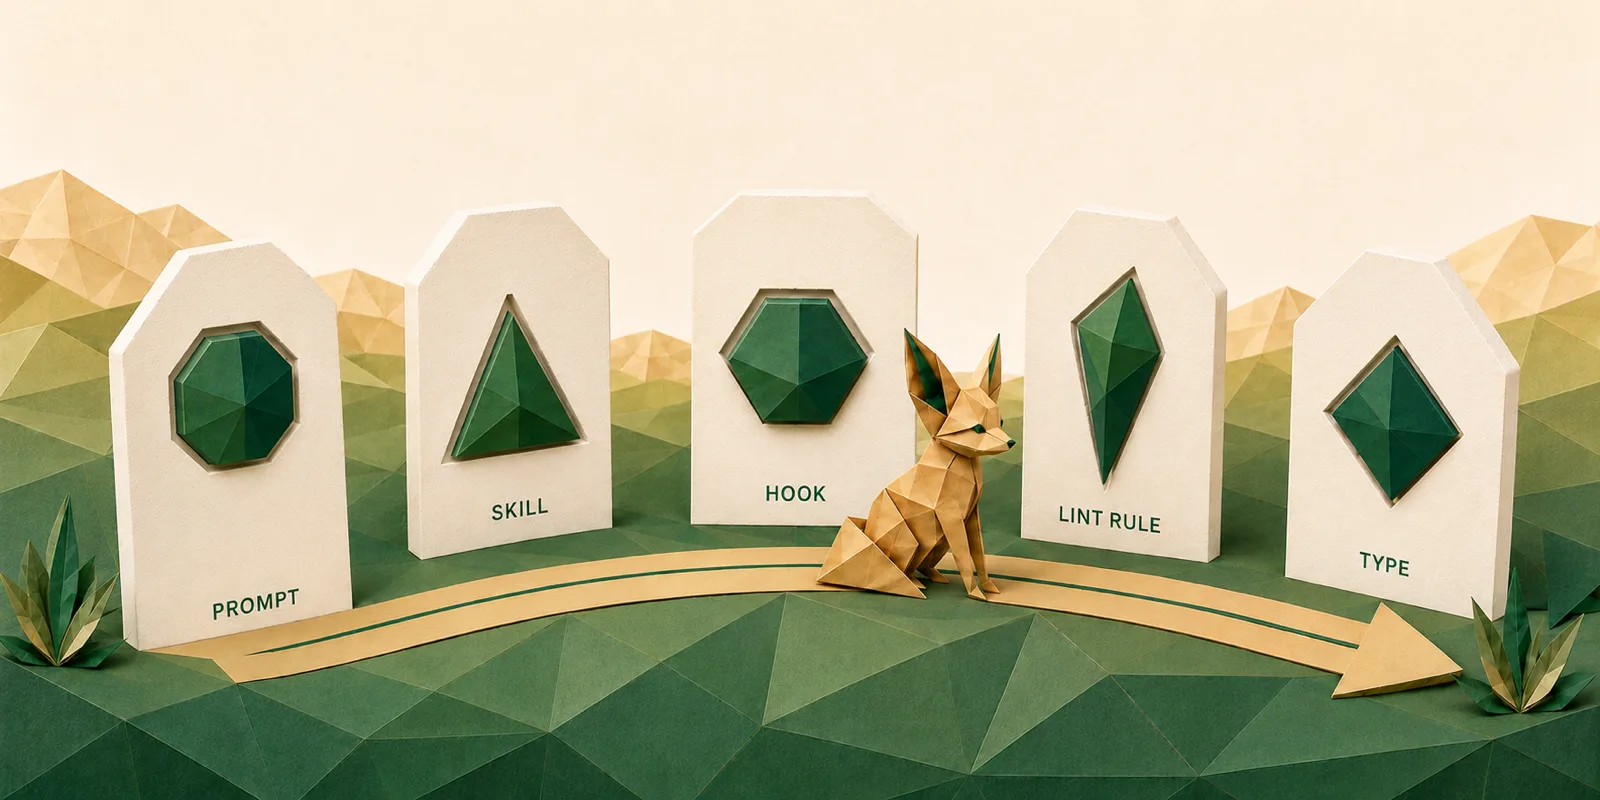
A prompt is advice for one task. A skill is reusable advice. A hook runs without being asked. A lint rule rejects a bad pattern. A type makes the invalid state unrepresentable. When the same correction appears three times in review, I try to move it one rung to the right.
Every coding agent starts by reading AGENTS.md. It is the standing prompt for the repository, a
way to give every agent the same starting context, but still only the first rung on that ladder.
Ours is 356 lines, most of them recording decisions we do not want to relitigate: /api/* is
reserved for a future public API; every form prevents duplicate submissions; use this primitive
rather than inventing another one.
As a prompt, AGENTS.md can explain what to do and why. But it can’t stop anyone from doing the
opposite. For decisions we care enough about, the build says no. We have 22 custom
oxlint rules in a package called vibes, including:
no-catch-500stops a handler from swallowing an error and hiding it from Sentry.require-job-group-in-loopcatches queue fan-outs that could let one tenant monopolize the workers.no-session-advisory-lockrejects session-scoped Postgres locks because we run PgBouncer in transaction mode.no-as-unknown-asrejects theas unknown as Tdouble assertion, which disables type checking without narrowing anything.
any is also an error outside tests. Both are ways to opt out of the type checking we chose
TypeScript for. The linter does not care whether the code came from me, a teammate, or an agent. It
fails in the same place and explains both the danger and what to do instead. Once we have paid to
learn a rule, enforcing it should not depend on the next reviewer remembering it.
Exceptions are explicit. A one-line suppression names the rule and gives the reason:
// oxlint-disable-next-line jsx-a11y/no-autofocus -- intentional focus on dialog open.
The most common signature of machine-generated slop is entropy. The fifth copy of a helper function
can be correct and still make the system worse because it introduces more maintenance cost, CI
execution time and surface area for drift. Yet no human reviewer remembers every similar helper
either. Our vibedupes utility, built on similarity-ts,
compares function syntax trees to detect functionally duplicate code. It checks changed functions on
each PR and runs a full-repository scan weekly. We tuned it until a match meant “fork” rather than
“similar shape,” because an ignored check is worse than no check at all.
That tuning threshold is still a judgment call, and the next person needs to know why we drew the line at 90% similarity. Which brings me to comments.
I owe comments a mea culpa. For most of my career, I believed good code should explain itself and
that a long comment was evidence of a bad abstraction. I still believe that when the comment merely
narrates what the code does. But no function name can tell you why four test shards are faster than
eight in this repository, why a threshold is 0.90 instead of 0.85, or which production incident
made a particular constraint necessary. Some of the comments I value most today are longer than
younger me would have tolerated because they preserve history, not mechanics.
There is no clever solution to comment rot. We make comments local, concrete, and falsifiable. A useful comment sits beside the decision and names the benchmark, incident, or rejected alternative behind it. Whenever the constraint can be expressed as a test, lint rule, or type, that mechanism does the enforcing; the comment explains why it exists. “Be careful here” will rot. “Four shards, not eight, because the critical path moves below 56 seconds” gives the next engineer something they can verify.
The threshold in vibedupes has exactly that kind of comment:
// Tuned against this repo: at 0.85/5 lines the report fills with `toNumber` and// one-line chart validators. Raising both leaves the forked-function findings.// 0.90 is where the pairs still read as copies rather than as functions that// merely share a shape — every fork family we set out to catch scores above it// (the three rate limiters are 99.33%, the four Snowflake JWT builders 99.59%).const DEFAULT_THRESHOLD = "0.90";const DEFAULT_MIN_LINES = "15";Without that history, lowering the threshold looks prudent. A new engineer and an agent share the same failure mode here: locally sensible reasoning without the history. The comment puts the history at the one place both are guaranteed to see it.
Documentation works the same way. It lives beside the code, and source comments link to it by path. The job-group rule points to the concurrency architecture doc. A person or agent can follow that link while working instead of guessing what somebody once wrote in a wiki. Context that cannot be reached from the checkout is not dependable context.
Fast feedback is a safety feature
Executable discipline has to be fast. When feedback is slow, people batch changes and work around checks; agents burn cycles or form wrong conclusions. A high-output repository must say no quickly, specifically, and as close as possible to the mistake. We make checks fast not by dropping them, but by testing the narrowest set of things that a change could break, and by not recomputing answers we already trust.
pnpm check is one command. CI uses Turborepo’s --filter='...[origin/main]' to test only affected
packages rather than the entire monorepo. A marketing-site change does not wait for more than a
thousand application test files. Locally, pnpm check:min applies the same idea to the current
diff. It asks Turborepo which packages the change can affect, then lets Vitest follow the module
graph to the relevant tests. Changing a single utility might run only one test file, taking just a
second or two, while changing a root configuration file will run the whole suite. Skipping
unnecessary work is the programmer’s kind of laziness.
When the application suite does need to run, its thousand-plus test files are sharded and run in parallel across multiple jobs, each with its own Postgres instance. This gives us parallelism without shared-database contention or cross-test interference. Nine out of ten PRs are green or red in under six minutes; the median CI run takes about three and a half minutes.
The other large win is refusing to repeat work. CI publishes successful task results to a shared
Turborepo cache that developers and agents can read but not write. A passing check from my Mac
should not be allowed to convince Linux CI that it can skip the same check. After every merge,
another workflow warms the cache for the exact tree on main, so pulling an unchanged main branch
and running pnpm check takes about a second.
Fast feedback keeps changes small. Fast checks catch the failures we know how to test. For everything else, we bias toward changes we can reverse. Feature flags make large changes reversible in production. Every feature flag records the date it entered the registry; after thirty days, an experiment is marked stale unless it is explicitly permanent, a category reserved for entitlements and policy controls. The default assumption is ship it, judge it, then delete it or make it the default.
We apply the same idea to schema changes: add a nullable column, backfill it, then enforce
NOT NULL. We use two or three PRs even when the whole change would compile as one. Each step is
easier to test, review, pause, and reverse.
The decomposition that makes a change safe is the same decomposition that makes it parallelizable. A change small enough to reason about is small enough to hand to an agent, review in minutes, and revert without ceremony. The careful version is the one that moves faster.
Every pull request gets an automated review
Static checks work best when we already know how to name the failure. There is still a middle ground between “the compiler rejects it” and “a human happens to notice”: a change can compile, pass every test, and still leave a stale assumption somewhere else in the repository. That is where automated code review earns its keep.
Greptile reviews every Sonora pull request against the rest of the
repository. It reads AGENTS.md, architecture docs, and rules retained from previous reviews
instead of treating the diff as its whole world. When a new picker component called the React Router
fetcher.submit from native buttons, it checked the implementation against the form-submission
rules in AGENTS.md and caught that duplicate submissions were not prevented. The next commit moved
those rows to our shared SubmitButton with an explicit pending state. In another PR, it connected
an additional database checkout to a previous, documented pool-exhaustion incident and told us to
share an existing transaction. Both are mistakes a line-by-line reading of the diff could easily
miss.
It also gets things wrong. It once complained that 200ms and 300ms animation durations bypassed our motion vocabulary when those were exactly the values the vocabulary prescribed. We replied, and it withdrew the comment. Automated review is a second reader, not an oracle. A finding has to describe a real failure mode well enough for us to verify it.
Review quality falls when a PR bundles unrelated work. Keeping each change cohesive gives Greptile, and the human after it, less irrelevant context to sort through.
A good automated-review finding should eventually make itself obsolete. If it catches the same class of mistake more than once, that is evidence to move the rule to the right on the ladder: from repository guidance to a hook, lint rule, or type. Automated review is useful in the gap, while the rule still depends on context we have not yet learned how to encode.
Make the repository remember
Engineering discipline compounds when each failure changes the path of the next change. On August 3, roughly 9,500 ungrouped sibling jobs contended on one database row. They exhausted the statement timeout, and their retained error text filled Valkey until workers could no longer boot.
The postmortem changed the system in several places. The fan-out path got a grouping primitive. The
concurrency behavior got an architecture doc. require-job-group-in-loop now rejects the pattern
that caused the incident, and its header comment records the date and consequence. The next engineer
sees that history while writing the loop, not after opening another postmortem.
That is discipline made executable: the incident changed the queue primitive, the documentation, and the set of programs the linter will accept. We paid for the lesson once. Not every failure deserves a lint rule; the durable response may be a type, a test, a different queue topology, or a smaller deployment. “Be more careful next time” is not durable.
That is how my job has changed. The repository settles formatting, imports, and approved primitives before a PR reaches me, leaving review for the spec and intent. The more important question is why the repository needed me to catch something.
Six merged PRs a day is not the target. It is a side effect of making confidence cheaper. The metric I care about is the time between “I know what I want” and “it is in production, and I am not nervous.”
The Slop Era will reward the team with the best engineering discipline, not the best prompt. What’s good for humans is good for machines: trustworthy evidence, explicit decisions, fast feedback, isolated work, and a codebase that remembers why. Machines do not need a separate discipline. They need ours, made executable. Build the discipline into the system.
Thanks to Gabriel Al-Harbi and Max Schwenk for providing feedback on drafts of this essay.